Why “seeing” isn’t “reasoning” in AI systems
You’ve probably seen a vision model produce fluent answers about an image, then fail on a tiny change: crop the corner, swap two labels, or ask for a count instead of a description. That’s the gap between “seeing” (detecting familiar patterns) and “reasoning” (using those observations to support a multi-step conclusion). Many models can recognize objects and textures well enough to sound confident, but they’ll still take shortcuts like reading text, latching onto background cues, or guessing from typical scenes.
Visual reasoning shows up when the model can justify relationships: which item is left of another, whether two parts connect, how many instances meet a condition, or what must be true given constraints in the image. Getting there isn’t free. It usually requires data that removes the easy cues, supervision that rewards intermediate steps, and tests designed to punish shortcut behavior—even when that means slower labeling and more careful evaluation.
Define the reasoning skills you actually need to teach
A common failure mode is training for “answers” when what you need is a small set of repeatable skills. Start by listing the operators your product actually depends on: grounding (point to the evidence region), attribute extraction (color, state, text), spatial relations (left/right/inside/overlap), counting with constraints (“how many red bolts”), comparison (“which is larger/closer”), and simple causal or functional inference (“is the switch on,” “is the door blocked”). Add temporal or procedural logic only if your images truly encode it (e.g., before/after panels, step photos).
Then define what “correct” means for each skill in your domain. “Count” might require handling occlusion; “compare” might require ignoring perspective; “read text” might be disallowed if it leaks the label. Writing these definitions upfront feels slow, but it prevents you from collecting a dataset that trains the model to guess from scene stereotypes while still scoring well on your headline metric.
Pick tasks and datasets that force real visual thinking
You’ll know you picked the right tasks when a model can’t get away with a generic caption. Favor question types that require locating evidence and applying an operator: “Which of these two parts is misaligned?”, “How many connectors are present on the top edge?”, “Is object A inside region B?”, “Which label corresponds to the broken seal?” Even better, use paired or counterfactual examples: same scene with one attribute flipped, or two nearly identical images where only the relevant detail changes. If the model’s answer changes for the wrong reason, you catch it early.
For data, mix three buckets: (1) curated real images from your domain with tight QA and “hard negatives” that look similar, (2) controlled synthetic or templated images to systematically cover edge cases (occlusion, clutter, scale), and (3) public visual reasoning sets for pretraining the skill, not the vocabulary. The harder you make shortcuts, the more annotation time you’ll spend drawing regions, writing precise questions, and auditing leakage.
Design supervision: labels, rationales, and intermediate steps
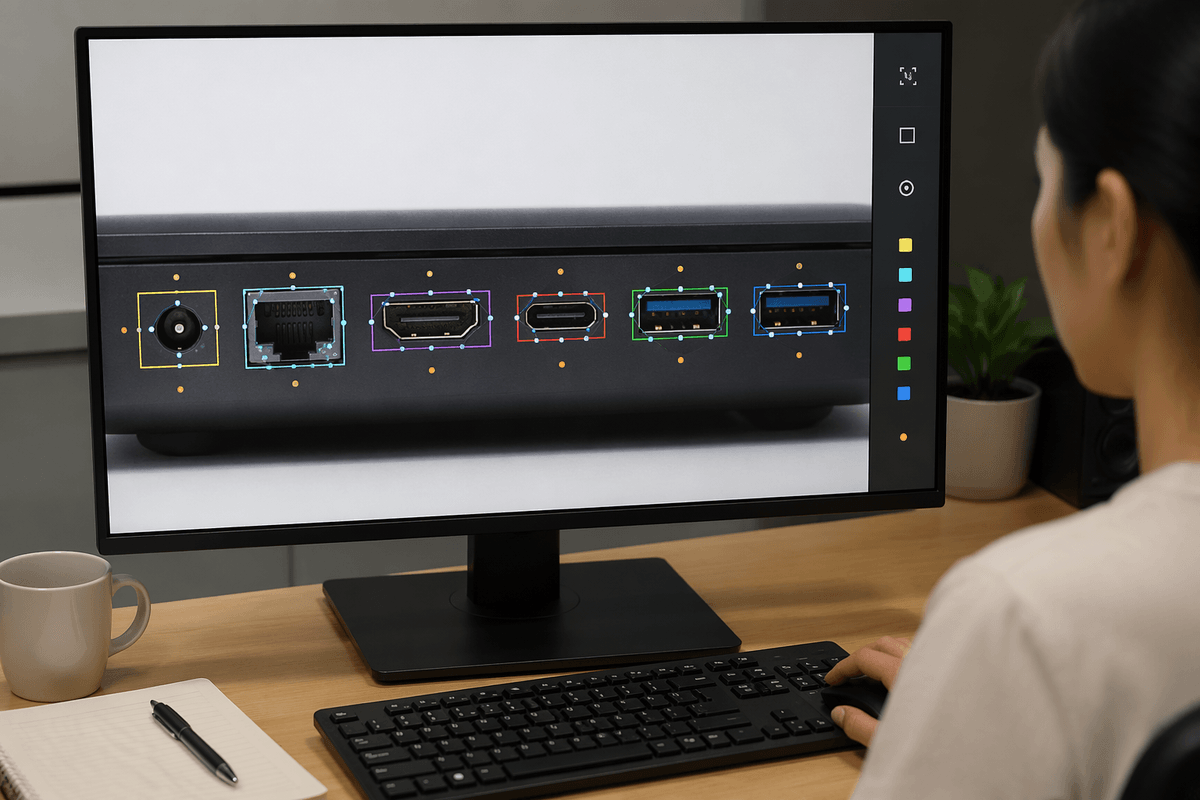
A familiar trap is labeling only the final answer (“3 connectors”) and hoping the model learns the right path. For visual reasoning, the supervision should mirror the operators you care about. Start with labels that pin the answer to evidence: bounding boxes, polygons, or even a coarse grid cell for “where to look,” plus a structured target like (object=connector, constraint=top edge, count=3). If you can’t afford full segmentation, low-cost click points or “highlight the evidence” masks from annotators still reduce guessing.
Add rationales, but keep them disciplined. Free-form explanations often turn into templated fluff and can leak the label. Prefer short, checkable intermediate steps: “Locate top edge,” “identify connector instances,” “exclude occluded shapes,” “count remaining.” When possible, supervise these steps directly with intermediate labels (lists of instance boxes, pairwise relations, ordered selections). The multi-stage annotations are slower, so reserve the heaviest supervision for the most failure-prone skills and sample the rest with lighter evidence-only labels.
Choose a training approach: prompting, fine-tuning, or hybrids
You’ll usually feel pressure to “just prompt it,” and prompting is a good first lever when the model already sees your domain well. Use structured prompts that force a procedure: ask for evidence locations first (boxes, grid cells, or textual anchors like “top-left corner”), then intermediate decisions, then the final answer. This is fast to iterate and cheap, but it’s brittle: small wording changes, longer contexts, or new camera angles can quietly degrade behavior.
Fine-tuning starts to pay off when you need consistent operator use (counting under occlusion, strict left/right, “no OCR”) across many variants. Train on your step-structured examples and hard negatives, and keep a held-out “shortcut” set that punishes guessing. The trade-off is operational: data QA, training runs, and regression testing become a real cadence.
Hybrids tend to work best in products: light fine-tuning to bake in the operators, plus prompting or a verifier model to enforce step order and calibration at runtime.
Evaluate like a skeptic: shortcuts, brittleness, and calibration
You’ll be tempted to trust aggregate accuracy, but visual systems can “win” by exploiting spurious cues: common co-occurrences (helmets imply bikes), watermark or UI artifacts, filename-embedded labels, or text in the scene doing all the work. Build targeted “shortcut” splits where those cues are removed or inverted: blur or mask text, swap backgrounds, crop out context, and include near-duplicate pairs that differ only in the relevant detail. If performance stays high when the evidence is missing, you’re measuring guessing.
Probe brittleness with controlled stress tests, not just more random data. Vary viewpoint, lighting, occlusion, and scale; add clutter; change camera pipelines; and test on different sites or device types. Track failure modes by operator (counting vs. spatial vs. comparison) so you can fix the right supervision, not just add more examples.
Finally, treat confidence as a product feature. Calibrate on a held-out set: when the model says 90%, it should be right about 9/10 times. If it can’t, add abstention thresholds, require evidence outputs, or run a verifier pass—accepting the cost in latency and annotation time.
A practical teaching pipeline you can iterate in weeks
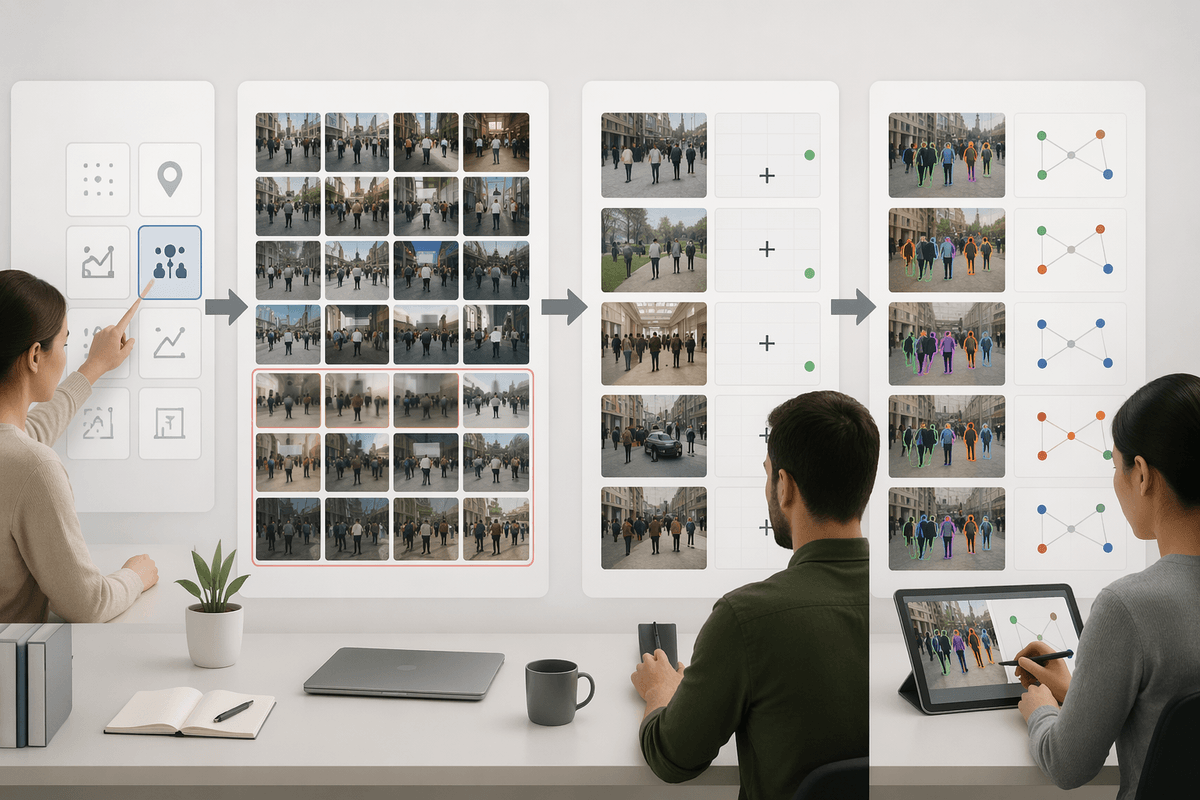
A workable weekly loop looks like: pick one operator (say, “count with a constraint”), assemble 200–500 examples spanning your real distribution, then add 50–100 “trap” cases designed to break shortcuts (masked text, swapped backgrounds, near-duplicates with only the relevant detail changed). Label lightly for most items (final answer + one evidence click or coarse region), and label heavily for the failures you care about (instance marks for counting, relation pairs for left/right). You’re not aiming for a perfect dataset; you’re aiming for fast signal on what the model is actually using.
Run three passes each cycle. Pass one is prompting with a fixed, procedural format and required evidence output; it establishes a baseline quickly. Pass two is a small fine-tune (or adapter/LoRA) on the step-structured subset plus hard negatives, keeping prompts constant so you can attribute changes to training. Pass three is a skeptic eval: operator-sliced metrics, shortcut splits, and a calibration check with an abstain option. Without frozen prompts, locked test sets, and error buckets, “iteration” turns into churn.
What “good enough visual reasoning” looks like in practice
You’ll feel “good enough” when the model is predictably right for the operators you care about, and predictably uncertain everywhere else. In practice that means: on your frozen shortcut splits (masked text, swapped backgrounds, near-duplicates), it keeps most of its baseline accuracy; on stress tests (new lighting, mild occlusion, different device cameras), it degrades gradually instead of collapsing; and when it’s wrong, its evidence output is obviously inconsistent, so you can detect and route the case.
“Good enough” also includes operational reality: you can retrain monthly without relabeling everything, the evaluator catches regressions by operator, and latency budgets survive a verifier pass or abstention logic. You’re shipping a bounded reasoning tool, not a general visual thinker.